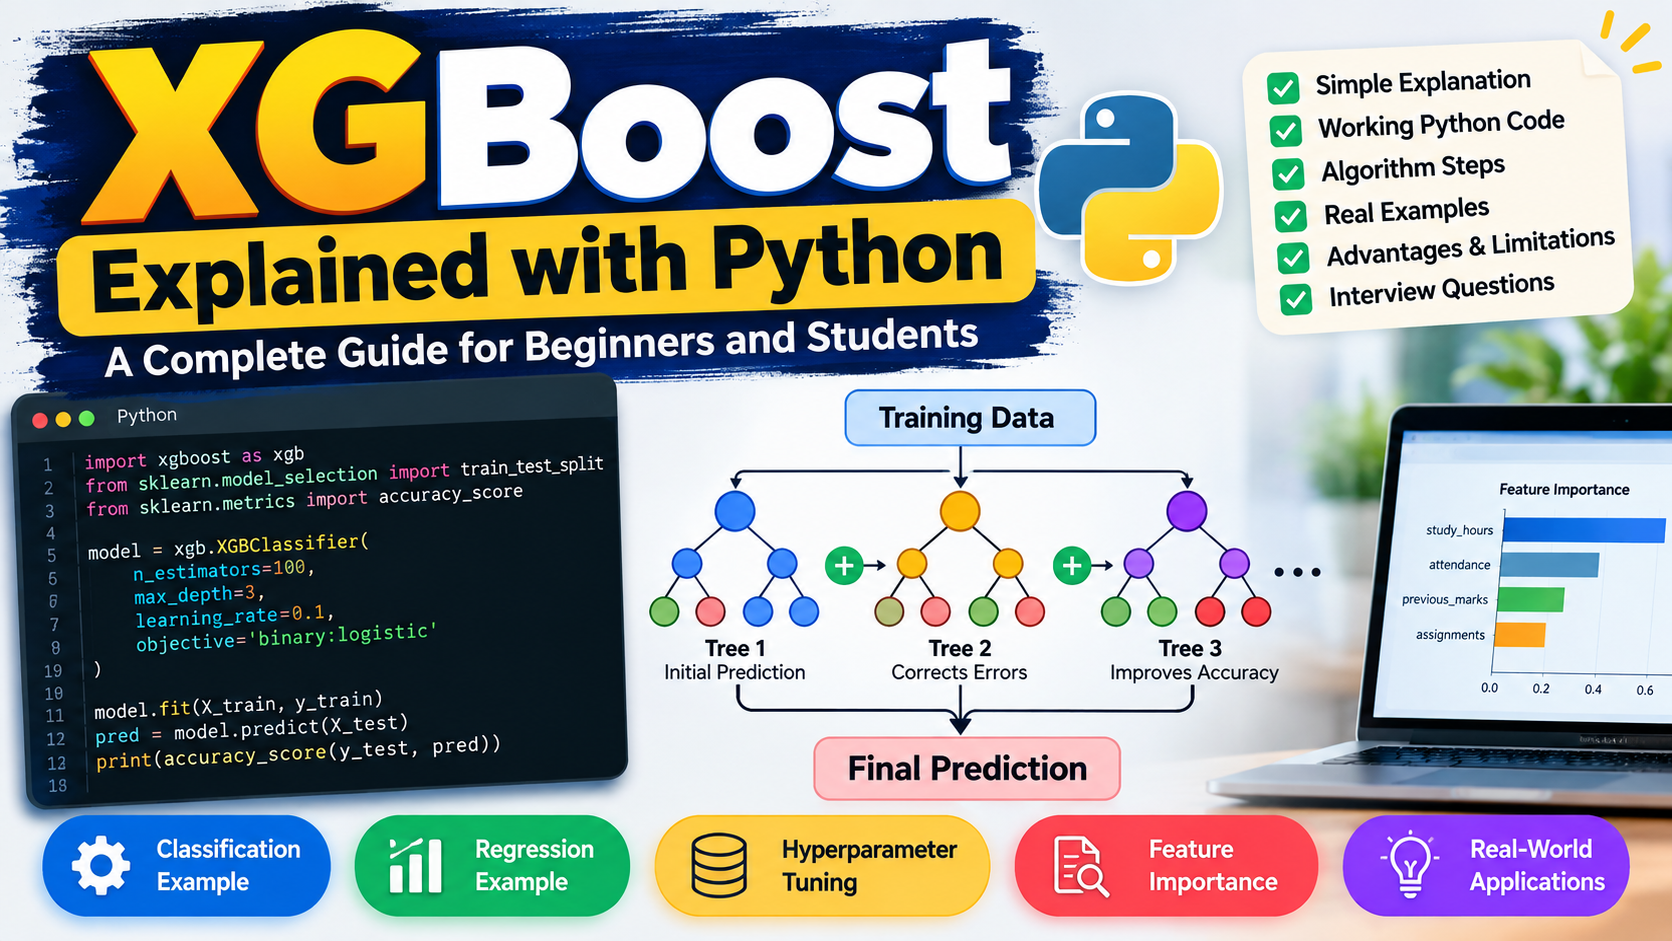
XGBoost Explained with Python A Complete Beginner’s Guide
Introduction to XGBoost
XGBoost is one of the most popular machine learning algorithms used for solving classification and regression problems. It is widely used in data science, predictive analytics, fraud detection, customer churn prediction, and many other applications.
The full form of XGBoost is Extreme Gradient Boosting. It is an optimized implementation of the gradient boosting technique that combines multiple decision trees to build a powerful predictive model.
If you are learning machine learning with Python, understanding XGBoost can help you build accurate models for real-world datasets.
In this tutorial, you will learn what XGBoost is, how it works, its advantages, practical examples, Python implementation, and common interview questions.
What Is XGBoost?
XGBoost is an open-source machine learning library that uses gradient-boosted decision trees to make predictions.
Instead of depending on a single decision tree, XGBoost builds a sequence of trees. Each new tree helps improve the predictions made by the existing model by learning from its errors.
For example, imagine you want to predict whether a student will pass an examination based on attendance, study hours, and previous marks.
A decision tree might make an initial prediction. XGBoost then builds additional trees to correct the model’s remaining errors. By combining these trees, it can produce a more accurate prediction.
XGBoost supports both regression and classification, along with other learning tasks.
What Is Gradient Boosting?
Gradient boosting is a machine learning technique that builds models sequentially.
Each new model attempts to reduce the errors of the combined model created so far. In gradient boosting, these improvements are guided by the gradient of a chosen loss function.
Consider a simple example of predicting house prices.
- The first decision tree predicts house prices.
- The model calculates the difference between its predictions and actual prices.
- A new tree learns patterns that can help reduce the prediction errors.
- More trees are added to improve the model.
- The final prediction combines the contributions of all the trees.
XGBoost builds on this idea with additional regularization, computational optimizations, and configurable training strategies.
How Does XGBoost Work?
The basic workflow of XGBoost can be explained in five steps.
Step 1: Make Initial Predictions
The model starts with an initial prediction based on the selected objective and training data.
Step 2: Calculate the Errors
It uses a loss function to measure how far the predictions are from the actual values.
Step 3: Build a New Decision Tree
The algorithm finds useful splits in the features to improve the current predictions. It uses first- and second-order gradient information for many of its standard objectives.
Step 4: Update the Model
The new tree contributes to the predictions, usually with a learning rate that controls the size of the update.
Step 5: Repeat the Process
The algorithm adds trees until it reaches the specified number of boosting rounds or another stopping condition.
The final prediction is formed by combining the contributions of the trees.
Important Features of XGBoost
1. High Performance
XGBoost includes optimized training procedures and can efficiently process many structured datasets.
2. Regularization
Regularization helps control model complexity and reduce overfitting. XGBoost provides L1 and L2 regularization options.
3. Missing Value Handling
XGBoost can learn how to route missing feature values during tree construction, which can simplify preprocessing for many datasets.
4. Feature Importance
The library provides several ways to measure feature importance, helping you investigate which features the trained model uses.
5. Parallel Processing
XGBoost can parallelize parts of tree construction and supports additional computational optimizations.
6. Multiple Learning Tasks
It supports common objectives for regression, binary classification, multiclass classification, and ranking.
XGBoost vs Decision Tree vs Random Forest
| Feature | Decision Tree | Random Forest | XGBoost |
|---|---|---|---|
| Basic approach | Single tree | Many trees trained independently | Trees built sequentially |
| Main purpose | Learn decision rules | Reduce variance | Improve predictions iteratively |
| Overfitting control | Pruning and constraints | Averaging and constraints | Regularization and tree constraints |
| Training | Usually simple | Trees can often train in parallel | Boosting rounds are sequential |
| Typical use | Interpretable rules | General-purpose predictions | Strong predictive performance on structured data |
No algorithm is best for every dataset. Always compare models using appropriate validation data and evaluation metrics.
Applications of XGBoost
XGBoost is frequently used in:
- Finance: Credit-risk modelling and fraud detection.
- Healthcare: Predictive modelling using structured patient data.
- Education: Student performance prediction.
- E-commerce: Customer churn and purchase prediction.
- Marketing: Customer response prediction.
- Real estate: House-price estimation.
- Business analytics: Sales and demand forecasting.